Healthy, but Not Reading: Moving DSMR-reader to Bletchley
DSMR-reader was Ready but collecting nothing. A failed migration, three layers of monitoring, and tracking PostgreSQL inserts without a GRANT
Introduction
DSMR-reader reads my smart meter. A small network reader connects to the meter's P1 port, DSMR-reader stores readings in PostgreSQL every few seconds, and the data flows to Home Assistant over MQTT and to PVOutput. For years, the whole thing ran as a Docker Compose stack, with its own PostgreSQL container. This week, it moved to the Bletchley Kubernetes cluster: the application into its own namespace, the database into the shared CloudNativePG cluster.
The migration succeeded on the second attempt. On the first, the pod started, became Ready, and served its web interface, but DSMR-reader wasn't collecting any readings. Kubernetes considered it healthy. In practice, it wasn't doing its job.
That failure exposed a gap in my monitoring. I had checks for whether the application was up, but nothing to tell me whether new readings were actually arriving. I wanted three layers of monitoring: one for the web interface, one for the data, and one to make sure the monitoring itself hadn't silently broken.
The second layer led to the most interesting part of the work. CloudNativePG can export custom SQL queries as Prometheus metrics, but querying the readings table directly would require a database GRANT that doesn't fit my goal of a fully Git-managed setup. The solution was to measure PostgreSQL's table statistics instead of reading the data itself.
🏠 This is part of the Homelab Journey series - building a production Kubernetes cluster from scratch.
- CloudNativePG Part 9
- Healthy, but Not Reading: Moving DSMR-reader to Bletchley (you are here)
This post builds on the CloudNativePG cluster from the CloudNativePG posts (most recently Part 9) and the Prometheus and Alertmanager setup from Cluster Observability Part 4.
The Trigger: A Pod That Was Healthy and Read Nothing
The migration plan had a rehearsal step: run the new version on the cluster against a copy of the database while the old one kept logging. The new pod had to start, run its database migrations and show the history, but it must not talk to the meter or publish anything. Two dataloggers on one meter, or two MQTT publishers feeding Home Assistant, is exactly what a rehearsal should not cause.
The Xirixiz image that DSMR-reader runs in has two settings for that, and I set both on the Deployment for the rehearsal:
kubectl -n dsmr-reader set env deploy/dsmr-reader \
  CONTAINER_RUN_MODE=server_remote_datalogger \
  DSMRREADER_BACKEND_HIBERNATE=True
CONTAINER_RUN_MODEdecides which services start inside the container. On the cluster it should bestandalone: web interface, backend and the datalogger that reads the meter, all in one pod.server_remote_dataloggeris meant for a setup where a separate datalogger elsewhere pushes readings into the server over its API, so the local datalogger is switched off.DSMRREADER_BACKEND_HIBERNATEstops the backend: no background jobs, no MQTT, no PVOutput uploads.
Together they give a pod that serves the web interface and does nothing else. Exactly right for a rehearsal.
The reset afterwards had to undo both. The hibernation I removed explicitly:
kubectl -n dsmr-reader set env deploy/dsmr-reader DSMRREADER_BACKEND_HIBERNATE-
The run mode I didn't reset. It stayed on server_remote_datalogger, and nothing complained: the Deployment was scaled to zero, so there was no running pod to inspect.
Just before cutover, I ran a go/no-go check that printed the run mode alongside the other settings:
0
CONTAINER_RUN_MODE=server_remote_datalogger
The 0 was the expected replica count. The line below it should have said standalone. I read the output, saw what I expected to see, and started the cutover.
The result, a few minutes later:
- The pod was Running and Ready. The startup, readiness and liveness probes all passed.
- The web interface loaded, through Traefik and Authelia, with all the history.
- The log said
svc-dsmr-datalogger | Disabled for mode server_remote_datalogger.
No new readings. I noticed because I was watching the dashboard, not because anything told me. I rolled back, and before the second attempt set the run mode back explicitly:
kubectl -n dsmr-reader set env deploy/dsmr-reader CONTAINER_RUN_MODE=standalone
The second attempt worked, with a gap of about four minutes in the readings.
Two things made this easy to miss. A setting changed with kubectl set env lives only in the cluster, so the manifest in git still said standalone and looked fine. And a check that prints a value is only a check if someone compares it with what it should be.
The rehearsal had already shown this in another form: with the backend deliberately hibernated, /healthcheck still answered 200. The health endpoint answers "is the web application up". For a service whose only job is to collect data, that is not the question: the question is "is the data arriving". The monitoring needs to answer both.
Three Layers
Each layer answers one question, and each one covers a way the layer before it can be wrong.
| Layer | Question | Signal |
|---|---|---|
| 1 | Is the web interface up? | Blackbox probe on /healthcheck |
| 2 | Are new readings still being stored? | Inserts into the readings table |
| 3 | Is the monitoring signal still present? | absent() on the layer 2 metric |
All three end up as alerts in the same rule group in prometheus-values.yaml.
Layer 1: Is the Web Interface Up?
The pod already has probes, but kubelet probes restart or remove a pod from the Service. They do not alert anyone. For an alert I use the blackbox exporter, the same way OpenBao's health endpoint is probed.
Probe the Service, not the Ingress
The first instinct is to probe the public name, https://dsmr.bletchley.vluwte.nl/healthcheck, since that tests the whole path. Here it tests nothing useful. The hostname is behind Authelia. Without a session, Authelia redirects to its login page, the blackbox exporter follows the redirect, and the login page answers 200. The probe would stay green with DSMR-reader completely down.
So the probe goes to the in-cluster Service:
- job_name: blackbox-dsmr-reader
  metrics_path: /probe
  params:
    module: [http_2xx]
    target: [http://dsmr-reader.dsmr-reader.svc.cluster.local/healthcheck]
  static_configs:
    - targets: ["prometheus-blackbox-exporter.monitoring.svc.cluster.local:9115"]
  relabel_configs:
    - source_labels: [__param_target]
      target_label: instance
    - target_label: __address__
      replacement: prometheus-blackbox-exporter.monitoring.svc.cluster.local:9115
Django checks the hostname
DSMR-reader is a Django application, and Django only answers requests for hostnames listed in ALLOWED_HOSTS. Everything else gets a 400. I had already run into this with the kubelet probes, which use the pod IP as the host: the pod never became Ready until the probes sent a Host: dsmr.bletchley.vluwte.nl header.
The blackbox probe sends the Service name as host, so that name has to be allowed too:
- name: DJANGO_ALLOWED_HOSTS
  value: dsmr.bletchley.vluwte.nl,dsmr-reader.dsmr-reader.svc.cluster.local
Before adding the scrape job, I tested the probe exactly as Prometheus will run it, through the exporter:
kubectl -n monitoring port-forward svc/prometheus-blackbox-exporter 9115:9115 &
curl -s 'http://localhost:9115/probe?module=http_2xx&target=http://dsmr-reader.dsmr-reader.svc.cluster.local/healthcheck' \
  | grep -E '^probe_(success|http_status_code) '
probe_http_status_code 200
probe_success 1
The alert
- alert: DSMRReaderUnhealthy
  expr: probe_success{job="blackbox-dsmr-reader"} == 0
  for: 10m
  labels:
    severity: warning
  annotations:
    summary: "DSMR-reader web interface is down"
    description: >
      DSMR-reader /healthcheck probe failed for 10 minutes.
      Check: kubectl -n dsmr-reader get pods; kubectl -n dsmr-reader logs deploy/dsmr-reader
for: 10m is long on purpose. The first start after a version upgrade runs database migrations, which took up to five minutes here, and an alert during a planned upgrade is noise.
This layer would have stayed green through the failed cutover. That is fine; it is not its question.
Layer 2: Is It Still Reading?
DSMR-reader stores every reading as a row in dsmr_datalogger_dsmrreading. If readings stop, that table stops growing. The question is how to get that into Prometheus.
The obvious approach: query the table
CloudNativePG can run custom SQL queries and export the results as metrics, through the same exporter that already produces the cnpg_* metrics. The obvious query is the age of the newest reading:
SELECT extract(epoch FROM now() - max("timestamp")) AS age_seconds
FROM dsmr_datalogger_dsmrreading;
Alert when it goes over five minutes, done. Except that it fails with a permission error.
Custom queries run as cnpg_metrics_exporter, a role CNPG creates for monitoring. It is a member of pg_monitor, which can read PostgreSQL's statistics and activity views, but it has no access to application tables. That is the right default: the monitoring role should not be able to read every tenant's data.
To make the query work, the role needs a grant:
GRANT SELECT ON dsmr_datalogger_dsmrreading TO cnpg_metrics_exporter;
Why that grant doesn't fit
Everything about this database is declared in git: the Cluster, a DatabaseRole for the owner, a Database resource, the password in OpenBao delivered by an ExternalSecret. CNPG reconciles all of it. But CNPG 1.30 has no way to declare table privileges. The Database resource manages schemas, extensions and foreign data wrappers; the DatabaseRole manages the role itself. A GRANT would be something I type once into psql.
That makes it hand-made state inside the database. It is not in the repo, nothing reconciles it, and the next person to rebuild this from git (most likely me, in a year) gets a monitoring query that fails with a permission error and no hint why. It also widens what the monitoring role can read, one table at a time, for every tenant that wants the same kind of check.
So the question changed from "how do I grant access" to "can I measure this without reading the table at all?"
Measure the statistics, not the data
PostgreSQL already counts what happens to every table. pg_stat_user_tables has a row per table with, among other things, n_tup_ins: the number of rows inserted. That view is exactly what pg_monitor is allowed to read.
A quick check that the counter actually moves, from my workstation as the tenant role, over the external name with full certificate verification:
CONN="host=postgres.vluwte.nl dbname=dsmrreader user=dsmrreader sslmode=verify-full sslrootcert=system"

psql "$CONN" -c "select n_tup_ins from pg_stat_user_tables where relname = 'dsmr_datalogger_dsmrreading';"
sleep 10
psql "$CONN" -c "select n_tup_ins from pg_stat_user_tables where relname = 'dsmr_datalogger_dsmrreading';"
 n_tup_ins
-----------
   1449021

 n_tup_ins
-----------
   1449023
Two rows in ten seconds. It doesn't tell me the age of the newest reading. Instead, it gives me a useful proxy: whether the readings table has received any inserts recently. If the datalogger normally stores readings continuously, a counter that stops increasing is a good signal that collection has stalled, without granting the monitoring role access to the readings themselves.
The custom query
Custom queries live in a ConfigMap. This one sits next to the other DSMR-reader manifests in apps/dsmr-reader/, in the databases namespace where the cluster runs:
apiVersion: v1
kind: ConfigMap
metadata:
  name: dsmr-reader-monitoring
  namespace: databases
  labels:
    cnpg.io/reload: ""        # query changes apply without restarting instances
data:
  queries: |
    dsmr_reader_readings:
      query: "SELECT n_tup_ins AS inserted FROM pg_stat_user_tables WHERE relname = 'dsmr_datalogger_dsmrreading'"
      primary: true
      target_databases:
        - dsmrreader
      metrics:
        - inserted:
            usage: COUNTER
            description: "Rows inserted into dsmr_datalogger_dsmrreading on this instance since its statistics were last reset"
A few details:
target_databases:pg_stat_user_tablesonly shows tables of the database you are connected to, so the query has to run insidedsmrreader.primary: true: the counter moves on the instance where the insert happens. Whether the replicas keep up is a different question, and CNPG already answers it: its default metrics include replication lag, and the existingcnpgalert group hasCNPGReplicaFailingReplication.- The metric name is built from the query name and the column:
cnpg_dsmr_reader_readings_inserted. cnpg.io/reload: changes to the query are picked up without restarting PostgreSQL.
The cluster then needs to know about the ConfigMap. That is the only change to the Cluster manifest (apps/databases/cluster.yaml):
spec:
  monitoring:
    customQueriesConfigMap:
      - name: dsmr-reader-monitoring
        key: queries
kubectl diff showed the new entry appended after CNPG's own cnpg-default-monitoring, which the operator adds by itself. After the apply, the generation went from 4 to 5 and none of the three instances restarted. A monitoring change is not one of the things that trigger a rolling update.
Within a minute the existing cnpg scrape job picked it up:
cnpg_dsmr_reader_readings_inserted{instance="10.244.3.100:9187", job="cnpg", namespace="databases", node="rock2", pod="bletchley-pg-1", role="primary"}
1449127
One series, from the primary. No new scrape job, no grant, and everything that makes it work is in git.
What normal looks like
sum(increase(cnpg_dsmr_reader_readings_inserted[10m]))
I expected 120: the datalogger is configured to sleep five seconds between readings. It settled at 100. The reason is that the sleep comes after storing a reading, and the datalogger then waits for the next telegram, which arrives about once per second. That makes roughly six seconds per reading, or 100 per ten minutes.
The graph also shows why I don't expect the metric to jump straight to its steady-state value: the ten-minute increase() window needs time to fill after the metric first appears.
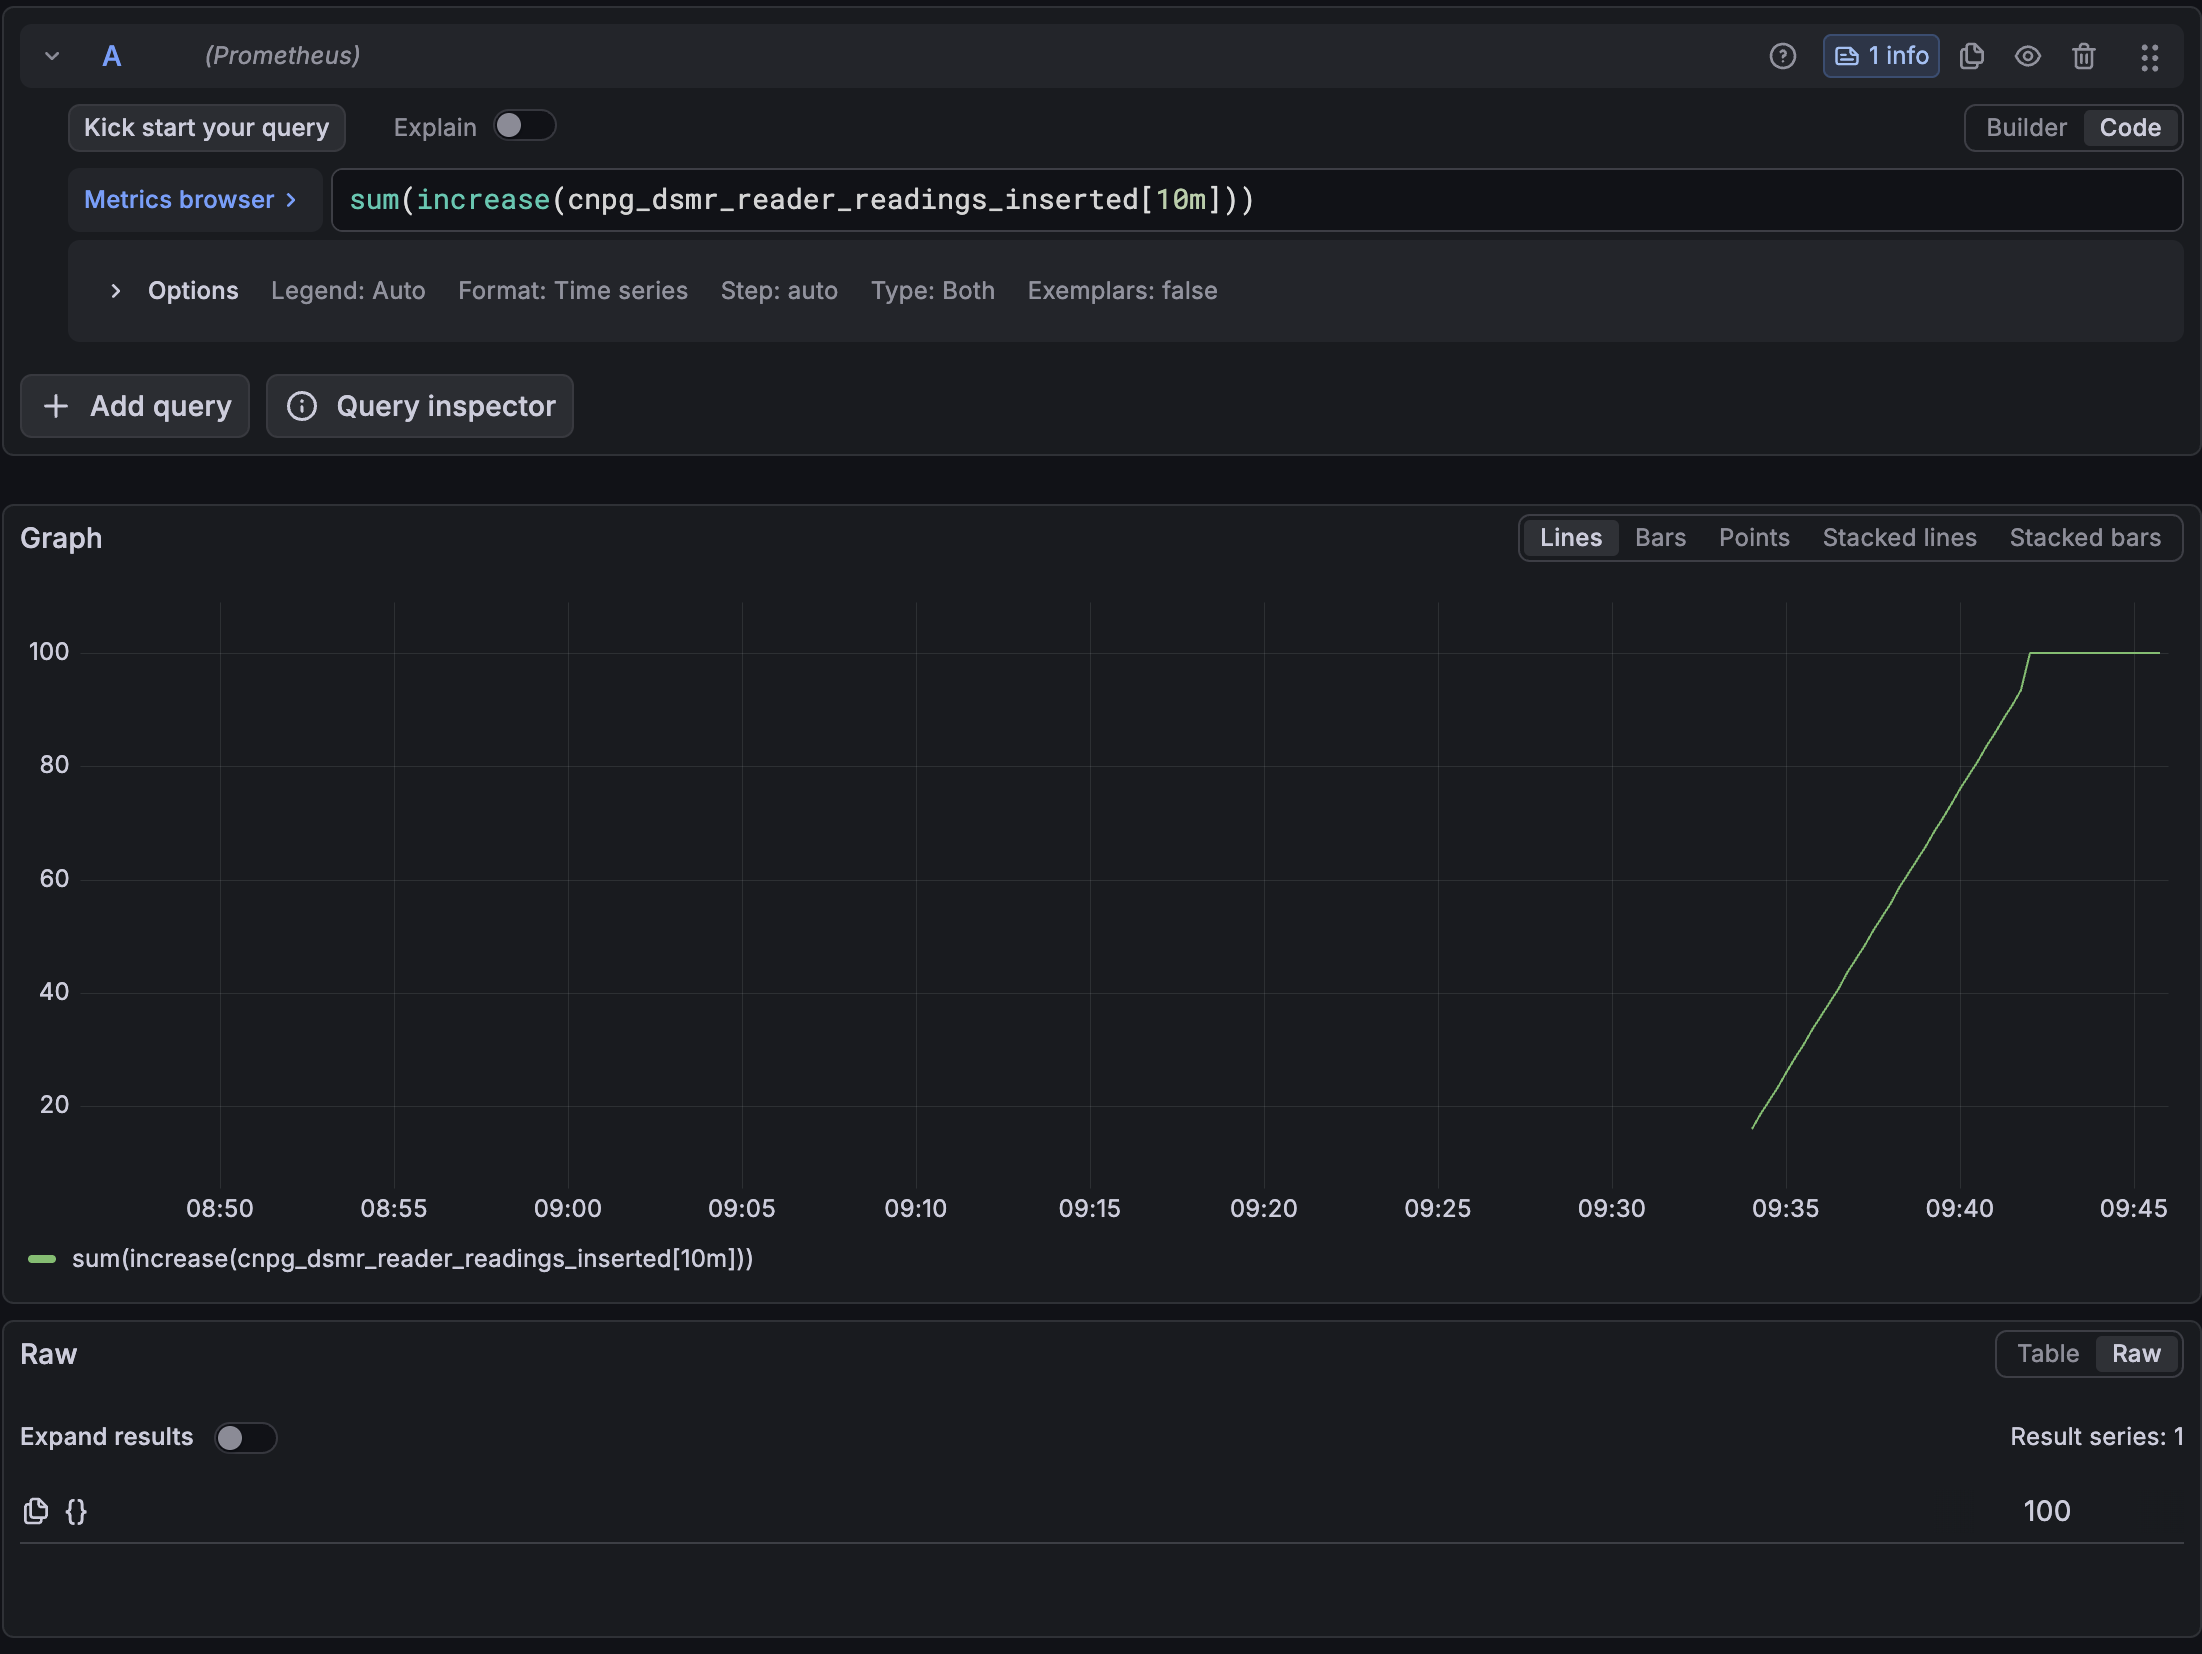
Both sum() and increase() serve a purpose here. increase() estimates the number of inserts over the last ten minutes, accounting for counter resets within each time series. sum() combines the results across the series exposed by the exporter.
That matters when the primary changes. The metric then comes from a different pod: the old series stops and a new one starts, with its own counter. For a few minutes the ten-minute window holds the end of one and the start of the other, so the sum can dip below 100 before it settles again. It shouldn’t drop to zero while readings keep arriving, and the for: 5m on the alert gives the window time to refill.
The alert
- alert: DSMRReaderReadingsStalled
  expr: sum(increase(cnpg_dsmr_reader_readings_inserted[10m])) == 0
  for: 5m
  labels:
    severity: warning
  annotations:
    summary: "DSMR-reader stored no new readings for 15 minutes"
    description: >
      No rows inserted into dsmr_datalogger_dsmrreading for 15 minutes.
      Check: kubectl -n dsmr-reader logs deploy/dsmr-reader | grep -i datalogger
      and the P1 reader at 10.0.5.16:23.
Ten minutes of window plus five minutes of for: the alert fires after about fifteen minutes without a single new row. This is the one that would have caught the failed cutover.
Layer 3: Is the Measurement Still There?
Layer 2 has a blind spot. If the custom query breaks, the ConfigMap reference disappears, or Prometheus stops receiving the metric, the readings counter may vanish altogether. In that case, sum(increase(...)) returns no series rather than a value of zero. An alert that checks only for zero inserts won't catch that situation.
The solution is a separate alert for the absence of the metric:
- alert: DSMRReaderReadingsMetricMissing
  expr: absent(cnpg_dsmr_reader_readings_inserted)
  for: 15m
  labels:
    severity: warning
  annotations:
    summary: "DSMR-reader readings metric is missing"
    description: >
      The CNPG custom query for dsmrreader returns nothing.
      Check cnpg_collector_last_collection_error and ConfigMap databases/dsmr-reader-monitoring.
This tells me that the expected measurement has disappeared, but not why. The CNPG exporter also exposes cnpg_collector_last_collection_error. According to the CNPG documentation, a failing custom query sets it to 1 while the other cnpg_* metrics continue flowing, which gives me a useful diagnostic signal when investigating the alert.
The Result
The alert rules live inside prometheus-values.yaml, as a YAML document embedded in a YAML file. A mistake in the indentation or in a PromQL expression doesn't show up until Prometheus fails to load the rules, after the upgrade. So after every edit to the rules I extract them with yq and let promtool check them before running helm upgrade (version pinned):
yq '.serverFiles."alerting_rules.yml"' apps/monitoring/prometheus/prometheus-values.yaml \
  > /tmp/rules.yaml && promtool check rules /tmp/rules.yaml
Checking /tmp/rules.yaml
  SUCCESS: 89 rules found
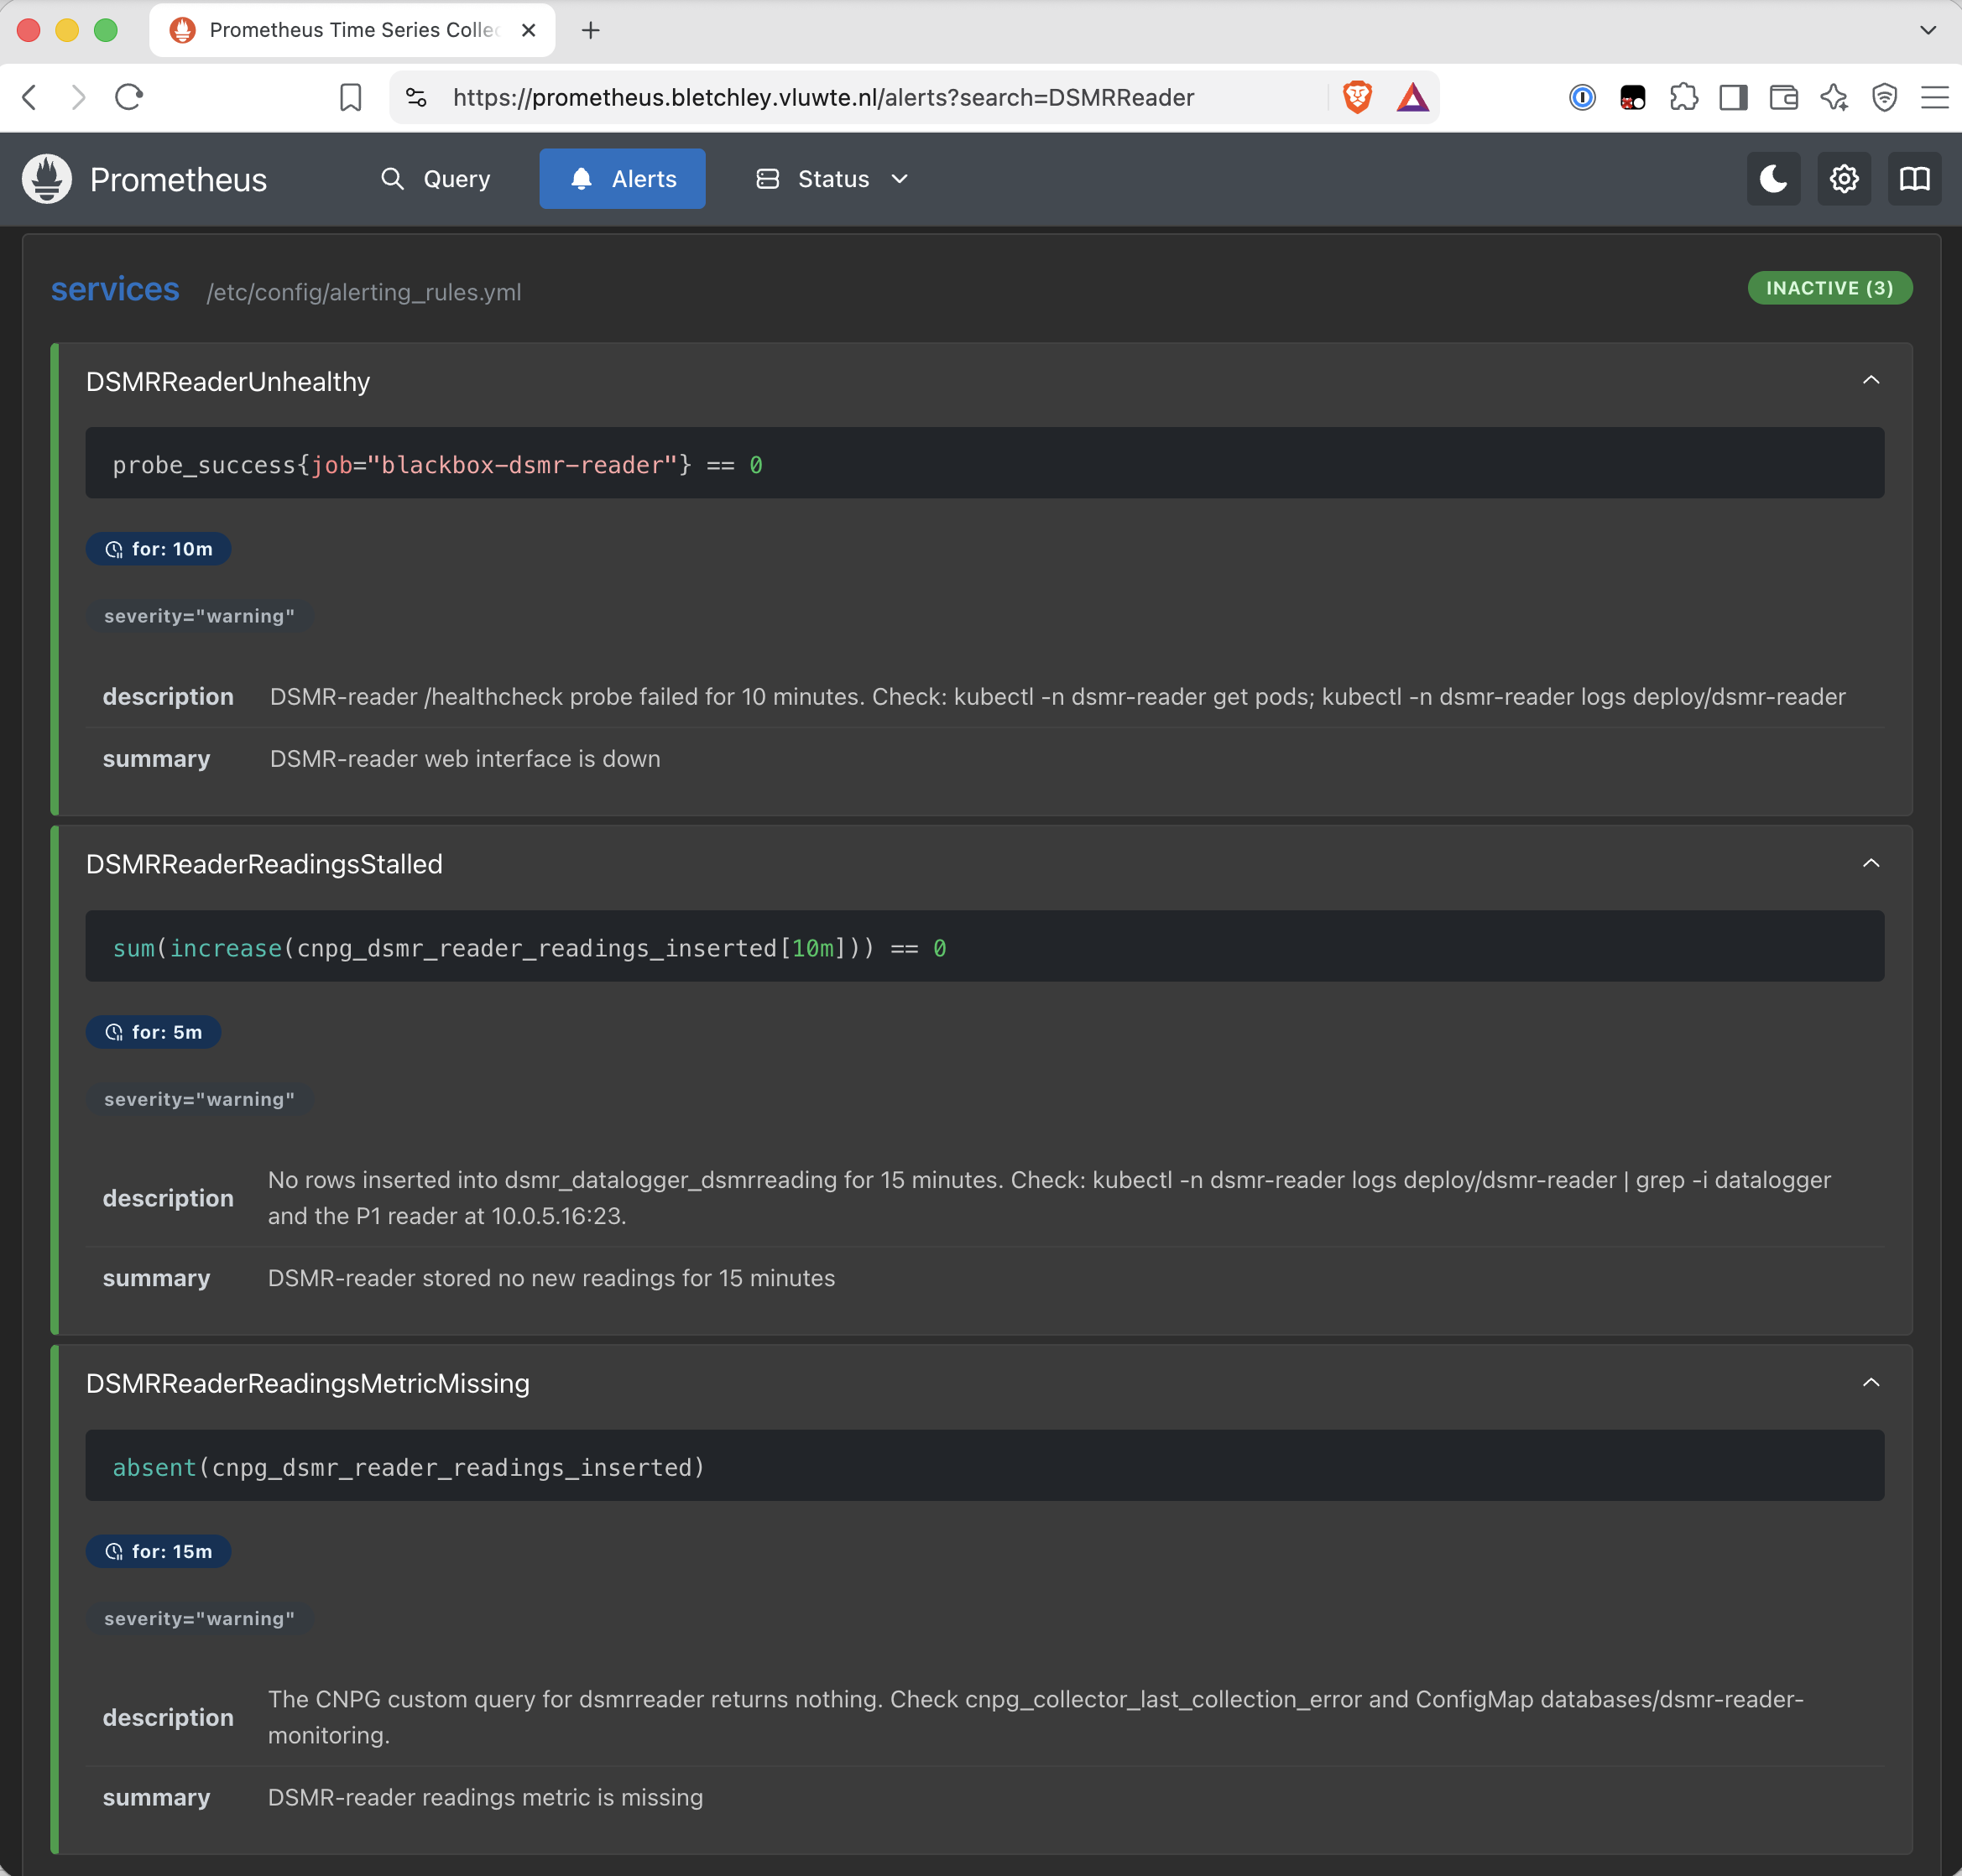
Back to the failed cutover. Layer 1 would have stayed green because the web interface was working. Layer 2 would have detected the stalled readings after roughly fifteen minutes. Layer 3 would have remained quiet in this particular failure because the metric itself was still present. That is the combination I want: healthy-but-not-reading fires one alert, a broken query fires a different one, and nothing stays silently green. Another tenant that wants this check needs a query in a ConfigMap and two alert rules.
Lessons Learned
- A health check answers "is it up", not "is it working". For an application that collects data, the useful signal is the data arriving.
- Don't probe through the authentication proxy. A login page answers
200too. Probe the in-cluster Service, and allow that hostname if the application checks it. - When a check needs a grant, look for a statistic first.
pg_stat_user_tablescounts inserts, updates and deletes for every table, andpg_monitorcan already read it. - CNPG custom queries keep monitoring declarative. A ConfigMap, three lines in the
Clusterspec, and alert rules: all in git, no restart, nothing typed intopsql. - Monitor the measurement as well as its value. An alert that checks only for a bad value can go silent when the metric disappears. Make missing telemetry an explicit failure mode.
- Every
kubectl set envneeds its own undo. A value set that way exists only in the cluster, not in git. Undo each one explicitly, and before going live, compare file and cluster withkubectl diff -f deployment.yaml: it would have shown the leftover run mode.
What's Next
- Soak: the old Docker stack stays stopped but intact for about two weeks. If nothing turns up, it gets removed.
- The same pattern elsewhere: any CNPG tenant with a table that should keep growing can get a query in a ConfigMap and two alert rules.
- Content pipeline: the next CloudNativePG part covers the internal certificate renewal at the end of October.
← Previous: Handling a Password You Never See
Questions or suggestions? Leave a comment below or reach out at igor@vluwte.nl.